Getting started with System One models in Swift
Fast, deterministic AI decisions with Apple Foundation Models
System One models like TypeSafe’s Jev are smart if statements: you pass in some context and a couple of questions, and they will send back an answer for each of the questions - in just a couple hundred milliseconds.
Let’s take a look how this works, why Jev is called a System One model, and how you can use this in your own apps using Swift and Apple’s Foundation Models framework.
Why is this even important?
As humans, we make decisions all the time - in fact, more than 30,000 per day! Not all of these decisions are life-changing, like whom to marry or whether you should get an iPhone 18 Pro or an iPhone Duo. Most of our decisions are micro-decisions, and we make them intuitively. In his book “Thinking, Fast and Slow”, Daniel Kahneman coined the term System 1 thinking for this kind of fast and intuitive thinking. On the other hand, slow and deliberate thinking is called System 2 thinking.
In software systems, we typically use if-then-else statements or switch statements to codify decisions. This is easy enough when the outcome of a decision can be computed using boolean logic, but it falls apart when you need to make a judgement call. Is this support ticket urgent? Is the sender of this email unhappy? Should we issue a refund?
You might have used LLMs to determine the best way forward for decisions like these, but LLMs are not well suited for this kind of problem: they’re (relatively) slow, and - more importantly - too expensive. Specifically when you need to make many of these decisions, for example when triaging a support queue or a user’s email inbox.
What are System One models?
System One models are built to make fast, structured decisions. Unlike LLMs, they skip token-by-token text generation entirely. Given an input state and bounded questions with predefined answer types, they predict probabilities across your questions in a single forward pass, returning a typed decision.
You provide context and one (or more) questions with a bounded answer space, and the model returns an answer from that bounded answer space, along with a confidence score.
Here is an example of a System One model request and response:
// Request
{
  "state": "Urgent: Primary PostgreSQL cluster CPU utilization exceeded 95% for 10 minutes. Standby warming up. Inspect query locks immediately.",
  "questions": {
    "requires_action": {
      "type": "noul",
      "instructions": "Does this email require an explicit user response or action?"
    },
    "category": {
      "type": "choice",
      "instructions": "Primary functional classification of the incoming message.",
      "criteria": {
        "security_alerts": "Security vulnerabilities, breaches, or infrastructure alerts",
        "billing": "Invoices, payments, or subscription issues",
        "work": "General workplace or project updates",
        "meetings": "Calendar invitations or scheduling requests",
        "newsletters": "Marketing emails, digests, or announcements"
      }
    },
    "urgency_score": {
      "type": "score",
      "instructions": "Priority rubric score: 0 = Low background, 1 = Normal routine, 2 = High priority, 3 = Critical emergency.",
      "criteria": [
        "Low background",
        "Normal routine",
        "High priority",
        "Critical emergency"
      ]
    }
  }
}

// Response
{
  "model": "jev-1.13.0",
  "answers": {
    "requires_action": {
      "type": "noul",
      "noul": 0.99
    },
    "category": {
      "type": "choice",
      "choice": "security_alerts",
      "probabilities": {
        "security_alerts": 0.96,
        "work": 0.02,
        "billing": 0.01,
        "meetings": 0.005,
        "newsletters": 0.005
      },
      "confidence": 0.96
    },
    "urgency_score": {
      "type": "score",
      "score": 3.0,
      "legend": {
        "0": "Low background",
        "1": "Normal routine",
        "2": "High priority",
        "3": "Critical emergency"
      },
      "probabilities": {
        "0": 0.0,
        "1": 0.01,
        "2": 0.05,
        "3": 0.94
      },
      "confidence": 0.94
    }
  },
  "elapsedMs": 42
}
Core concepts of System One models
To understand this better, let’s look at the key concepts of System One models. At the heart of every System One model is the question.
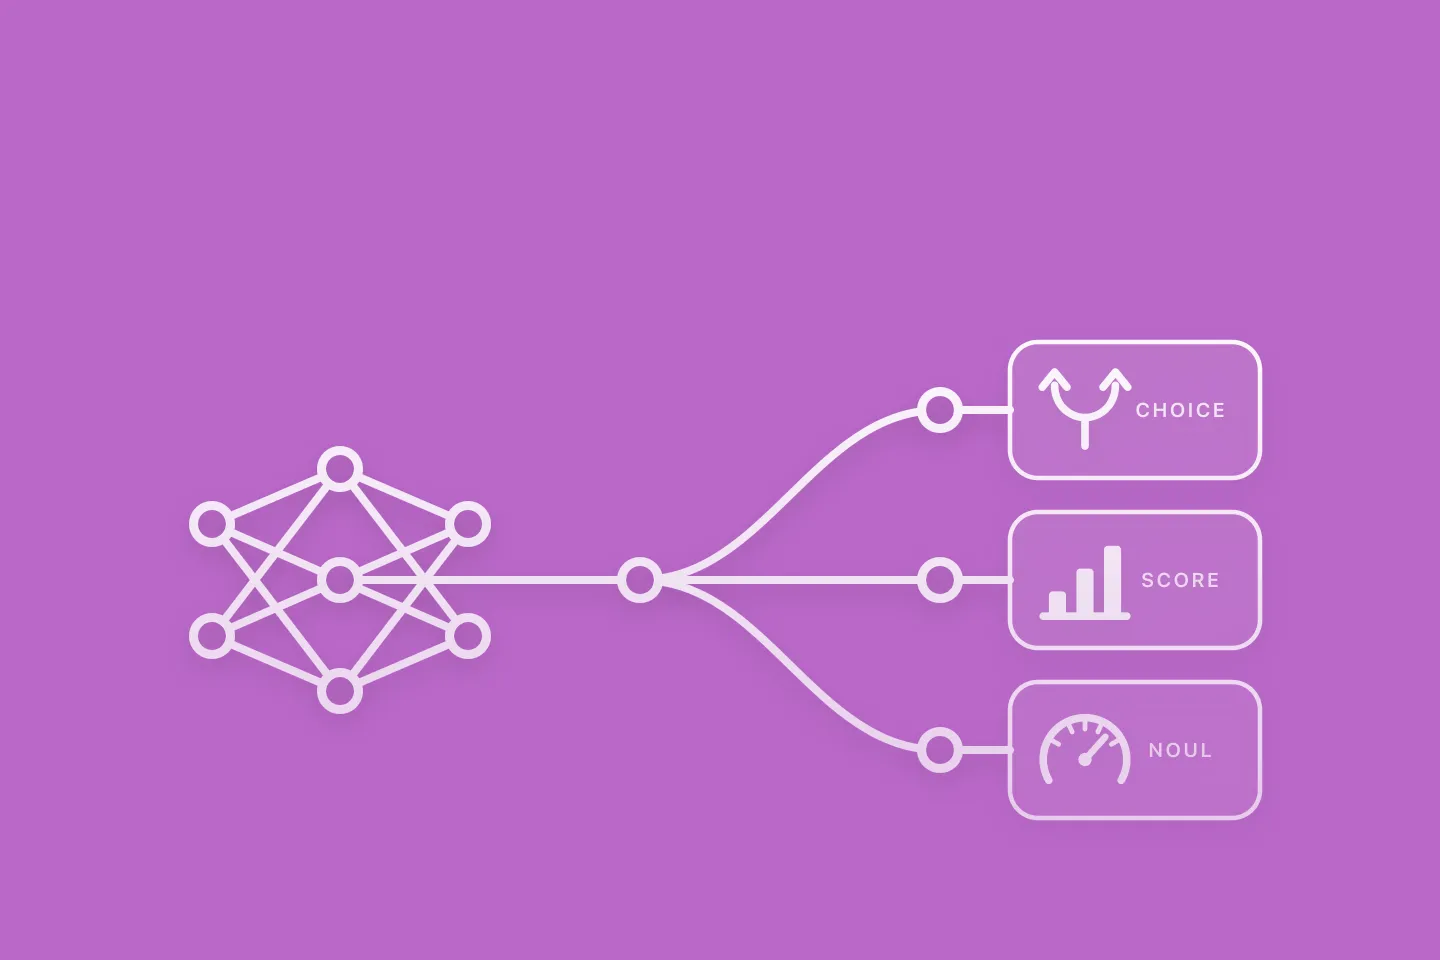
System One models support three types of questions: Choice, Score, and Noul.
| Type | Question | Result |
|---|---|---|
Choice | Which of the following options? | choice, probabilities, confidence score |
Score | Where on this scale? | score, legend, probabilities, confidence |
Noul | Is this true? | noul, probability between 0 and 1 |
Choice: Pick an option
A choice evaluates the input against a set of options and selects the best fit. Use it when the answer to a question is one of a fixed set of options with no inherent order. For example, “which department handles this ticket”, “which language is this email written in”, or “which of the following links leads to the checkout page”.
{
  "department": {
    "type": "choice",
    "instructions": "Which department should handle this ticket?",
    "criteria": {
      "billing": "Payment, invoicing, or subscription issues",
      "technical": "Bugs, outages, or integration problems",
      "sales": "Pricing, plan upgrades, or contract questions"
    }
  }
}
The answer includes the selected option, a confidence score, and the full probability distribution for all options you provided:
{
  "department": {
    "type": "choice",
    "choice": "technical",
    "probabilities": {
      "billing": 0.02,
      "technical": 0.95,
      "sales": 0.03
    },
    "confidence": 0.95
  }
}
Score: Rate on a scale
A score is useful when the answer sits on a spectrum, for example “how frustrated is the sender of this email”, “how familiar is the candidate with this technology”, or the severity of a bug.
{
  "frustration": {
    "type": "score",
    "instructions": "How frustrated does the customer appear?",
    "criteria": [
      "Calm, polite, or just stating facts",
      "Mildly annoyed or impatient",
      "Frustrated, but civil and constructive",
      "Extremely angry, aggressive, or using strong language"
    ]
  }
}
The criteria array goes from low to high, and each entry (0-indexed) is its level number. The answer contains this mapping in the legend field. It also contains the probabilities for each criterion. The score field is a numeric value, calculated as a probability-weighted mean of the level positions.
{
  "frustration": {
    "type": "score",
    "score": 1.82,
    "legend": {
      "0": "Calm, polite, or just stating facts",
      "1": "Mildly annoyed or impatient",
      "2": "Frustrated, but civil and constructive",
      "3": "Extremely angry, aggressive, or using strong language"
    },
    "probabilities": {
      "0": 0.05,
      "1": 0.08,
      "2": 0.87,
      "3": 0.0
    },
    "confidence": 0.87
  }
}
Noul: Yes or no
A noul answers a yes / no question, and returns the probability that a statement is true on a scale from 0.0 to 1.0.
TypeSafe has never published an official etymology for the name: community documentation like System One Models and Learn Jev treats it as a coined term, while developers debate whether it is a portmanteau of “no” and “bool” (a probabilistic boolean) or a blend of “no” and “null”. In practice, you can think of it as a calibrated, probabilistic boolean.
Use noul for guardrail checks, policy validations or any other types of question that can be answered with yes or no: “is this a destructive command”, “does the sender of this email ask for a refund”, “is there an email address in this comment”.
{
  "refund_requested": {
    "type": "noul",
    "instructions": "Does the sender of this email ask for a refund?"
  }
}
The answer is a simple number indicating the probability that the answer is yes. A value close to 1 means “the answer is a solid yes”, a value close to 0 means “it’s a solid no”, and an answer somewhere in the middle means the model isn’t sure.
{
  "refund_requested": {
    "type": "noul",
    "noul": 0.98
  }
}
Because the probability score itself is an expression of the uncertainty, there is no separate confidence field in the response.
Asking multiple questions
You can ask several questions at once, as long as they are about the same context. System One models evaluate every question in parallel. Asking more questions barely changes the response time.
And since the answer space is bounded to exactly the three primitives discussed above, System One models don’t hallucinate. You also don’t have to worry about the answer not being compliant to any JSON schema.
Asking doesn’t hurt
My dad always told me that it can’t hurt to ask (or as the German saying goes, “Fragen kostet nichts”, literally “asking costs nothing”). While using Jev isn’t entirely free, it is dirt cheap: you pay 0.042 USD per million input tokens, and the output is indeed free of charge.
Mapping to Apple Foundation Models
You’ve probably noticed that the three types of questions map nicely to Swift types:
noulmaps toBoolchoicemaps toenumscorecan be mapped to a range
And since Apple opened their Foundation Models framework to other model providers, we can create a LanguageModel implementation that allows us to use Jev (and other System One models) using the Foundation Models framework APIs we’re already familiar with.
Let’s look at a practical example: building an intelligent email triage system. The questions we need answers for are:
- Should the user take action on this email?
- Which category does this email belong to?
- What’s the priority of this email?
First, let’s define the different categories of emails (meetings, newsletters, work, billing, security alerts). For bounded options like this, we can use a choice. To express this in Swift, we’ll use an enum :
import Foundation
import FoundationModels
import JevFoundationModels

@Generable
enum EmailCategory: String, Sendable {
    case securityAlerts = "security_alerts"
    case billing
    case work
    case meetings
    case newsletters
}
By marking the enum as an @Generable, we tell the Foundation Models framework to use this type for structured generation.
We can now put together our questions by using an @Generable Swift struct:
@Generable
struct EmailTriageDecision: Sendable {
    @Guide(description: "True if this email requires an explicit user response, decision, or action.")
    var requiresAction: Bool

    @Guide(description: "Primary functional classification of the incoming message.")
    var category: EmailCategory

    @Guide(
        description: "Priority rubric score: 0 = Low background, 1 = Normal routine, 2 = High priority, 3 = Critical emergency.",
        .range(0...3)
    )
    var urgencyScore: Int
}
Making decisions in Swift
Now that we’ve created our typed decision structure, we can call the model via Apple’s Foundation Model framework. This is a three-step process:
- Initialise the connection to the Jev model
- Instantiate a
LanguageModelSessionand injectJevLanguageModel - Call
session.respond
Let’s first instantiate JevLanguageModel:
let model = JevLanguageModel(apiKey: ProcessInfo.processInfo.environment["TYPESAFE_API_KEY"]!)Note: Never embed API keys for cloud services in your client-side applications. Embedded keys can easily be extracted from your app’s binary, allowing malicious actors to use your API keys for their purposes.
Refer to the documentation of peterfriese/system-one-foundation-models for secure ways to call Jev and other System One models.
Next, set up a language model session:
let session = LanguageModelSession(model: model)Following this, let’s provision some sample data that the model can operate on.
let email = """
Subject: Urgent: Production Database High CPU Alert
From: ops-alerts@company.internal

Alert: Primary PostgreSQL cluster CPU utilization exceeded 95% for 10 minutes.
Automated failover standby is warming up. Please inspect active query locks immediately.
"""
Finally, we can prompt the model to request a typed decision:
let response = try await session.respond(
    to: email,
    generating: EmailTriageDecision.self
)

let triage = response.content
print("Requires action: \(triage.requiresAction)") // true
print("Category: \(triage.category)")              // .securityAlerts
print("Urgency score: \(triage.urgencyScore)")     // 3
Notice how the call to session.respond(to:generating:) is literally Apple’s Foundation Models framework method without any modifications or proprietary wrappers. It’s the same API you are already familiar with if you’ve been using Apple’s Foundation Models framework before.
And thanks to structured generation, the result of this call is guaranteed to be an instance of EmailTriageDecision .
Using confidence scores
Even though we received a cleanly typed answer, real-world decisions exist on a continuous spectrum of confidence.
System One models return a confidence score for choice and score questions. The package surfaces this telemetry through extensions on Apple’s LanguageModelSession.Response, allowing you to inspect calibrated confidence and probability distributions directly:
// Access calibrated confidence per question directly from the response
if let confidence = response.confidence(for: "category") {
    print("Category routing confidence: \(confidence)") // e.g. 0.96

    // Flag for human review if confidence falls below our threshold
    if confidence < 0.75 {
        print("Confidence is below acceptable threshold. Routing to manual review folder.")
    }
}

// Inspect calibrated boolean probability directly
if let actionProbability = response.probability(for: "requiresAction") {
    print("Action probability: \(actionProbability)") // e.g. 0.99
}

// Or inspect the full probability distribution for a choice
if let categoryProbabilities = response.probabilities["category"] {
    print("Probabilities: \(categoryProbabilities)")
}
Based on the confidence, you can decide if your code should directly act (for high confidence scores), ask the user for confirmation, or route to a slower system for further processing.
Where you draw the boundaries depends on the risk profile of the decision. For destructive actions, you will definitely want to only act automatically if the confidence score is very high.
Conclusion
When you have a hammer, everything looks like a nail. It’s easy to fall into the trap to use LLMs for every task. However, despite being very powerful, they’re not suitable for all types of tasks.
System One models are a strong alternative for many tasks, like routing, classification, priority checks, and probability checks.
As you saw in this blog post, Apple’s Foundation Models framework provides a unified API that makes using different models and even different types of models easy.
And with Dynamic Profiles, you can even use different models in the same AI workflow.
In addition to Jev, SystemOneFoundationModels supports other System One models as well - including on-device models like Laya, which allows you to run ultra-fast decisions on Apple’s Neural Engine. Check out the repo for more details and sample apps.
Apple Foundation Models: Hybrid AI with Dynamic Profiles
Have your cake and eat it, too
Agentic Coding in Xcode with Gemini CLI
Build apps with AI assistance in Xcode using Gemini CLI
Turn Your Photos Into Miniature Magic with Nano Banana
Build stunning image generation apps in iOS with just a few lines of Swift
Reverse-Engineering Xcode's Coding Intelligence prompt
A look under the hood